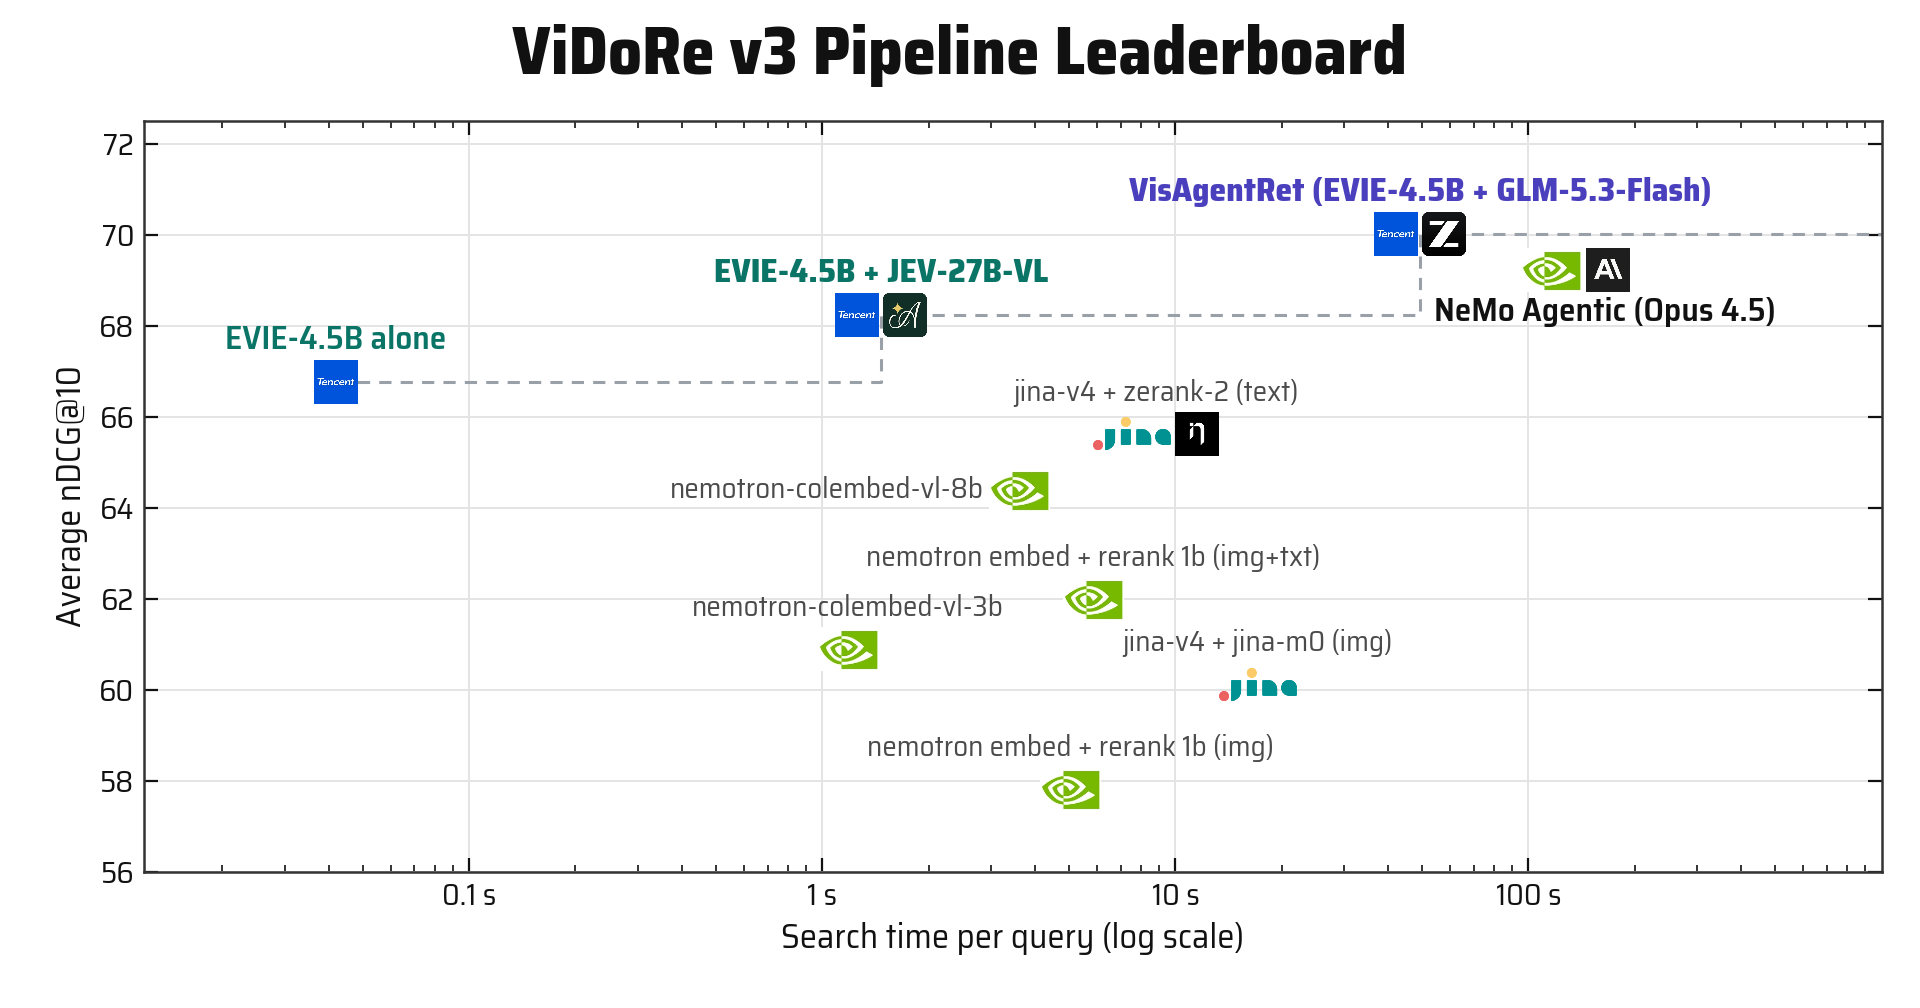
The Global Performance Tuner is a feature for automatic performance tuning released in NVIDIA TensorRT 11.1. It provides automatic, accuracy-aware and end-to…
The Global Performance Tuner in TensorRT 11.1 represents alternative scheduling strategies as explicit, searchable build routes composed of compiler knob combinations.
TensorRT exposes C++ APIs to apply a fixed build route, inspect the current route, and discover the full tunable configuration space of more than 200 knobs with their allowed values and defaults.
Deploying a trained neural network involves more than translating each operator into a GPU kernel. It is a compilation problem with many legitimate answers.
NVIDIA TensorRT builds inference engines by making interdependent scheduling decisions across graph transformations, fusion, implementation selection, memory placement, and quantization.
A mathematical framework models compilation as a builder algorithm generating candidate solutions and a searching algorithm selecting the fastest feasible one under accuracy constraints.
Encountering a new paper can change a research idea's trajectory.
The researcher may discover that someone has already addressed their proposed contribution, or find an unresolved problem in the paper that inspires a new direction of inquiry.
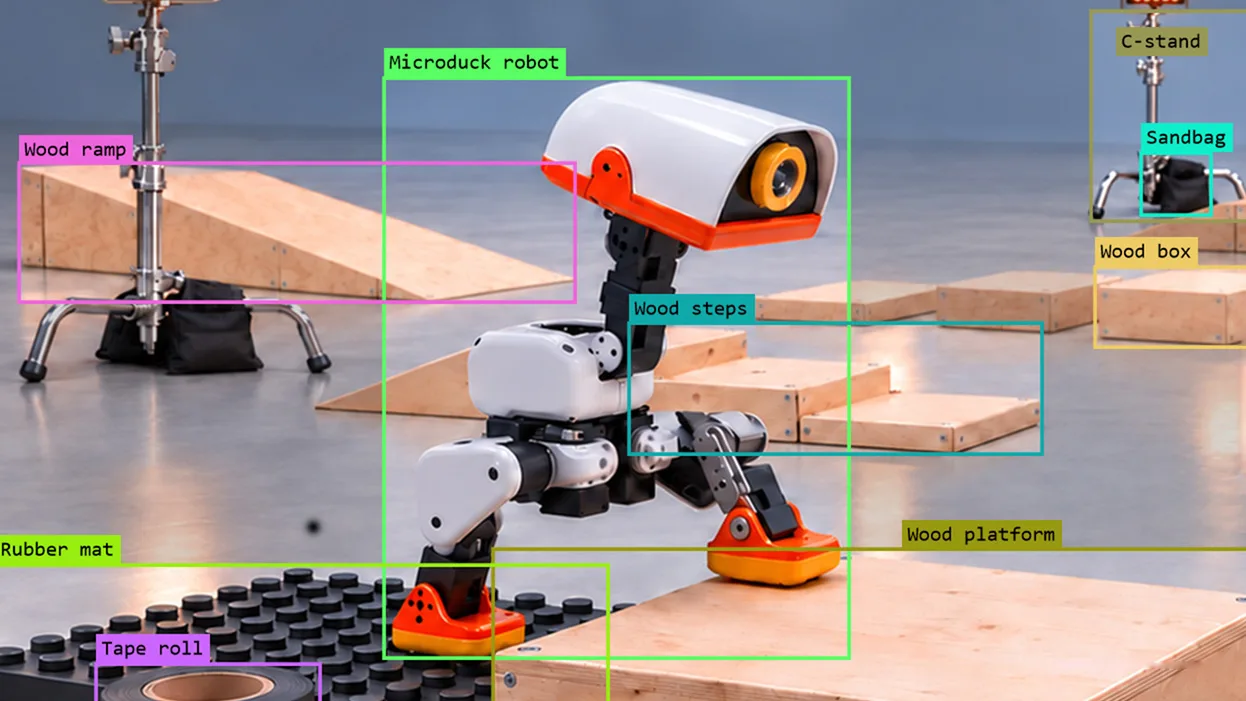
Teaching a robot to navigate an obstacle course requires more than a walking policy. It must perceive its surroundings, maintain balance, and adjust its actions…
NVIDIA RTX Spark serves as a local development hub where AI agents such as Hermes and Nemotron 3.5 Bolt translate a prompt into a step-by-step project plan for a simulated Microduck obstacle course.
Astra creates 3D simulation assets from the plan, enhancing references with cloud image editing, modeling geometry in FreeCAD, applying materials in Blender, and exporting editable models and USD assets for the environm…
Back to Articles Community Article Published October 23, 2026 Upvote 31 +25 Yihang Luo Luo-Yihang Follow Zunnan Xu kkakkkka Follow Shangchen Zhou sczhou Follow LAN YUSHI yslan Follow Kang Liao KangLiao Follow Gong Zerui…
Take a few photos of a room, and Mundo turns them into a world you can explore and simulate.
Takeaway : A5 is a proactive personal assistant that understands you better the more you use it.
Through ongoing interaction, it builds and updates its understanding of you and your projects, applying past preferences, experience, and decisions to new tasks.
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
Back to Articles Published October 23, 2026 Update on GitHub Upvote 6 David Corvoysier dacorvo Follow In a previous post , we introduced TorchNeuron, the native PyTorch backend for AWS Trainium (the torch-neuronx packag…
With it, Transformers runs its own modeling code on Trainium, as it does on any other device, so any Transformers model on the Hub may run.
A Blog post by TNG Technology Consulting GmbH on Hugging Face
Back to Articles Community Article Published October 15, 2026 Upvote 7 +1 Henrik Klagges TNGHK Follow tngtech Thomas Endres thomas-endres-tng Follow tngtech Robert Dahlke rbrt Follow tngtech Fabian Klemm fabiankTNG Foll…
TNG Technology Consulting was pleased to be granted early access to this model to run some early-adopter experiments with it.
Back to Articles Community Article Published October 22, 2026 Upvote 7 +1 Kunal Tangri ktangri Follow Farsight-AI Adrian Lepers AdrianLepers Follow Farsight-AI Jeff Boudier jeffboudier Follow Farsight-AI Open models are…
How valuable AI becomes inside a firm now depends less on the model and more on where it's allowed to run.
GPU applications are processing ever-growing datasets with increasingly powerful accelerators. According to the 2025 Stanford AI Index, compute for notable AI…
NVIDIA KvikIO provides high-level Python and C++ interfaces that sit above the cuFile C API to enable accelerated file I/O into GPU memory.
The library and cuFile make independent path-selection decisions: KvikIO chooses whether to invoke cuFile, while cuFile determines whether the transfer uses the accelerated nvidia-fs kernel module or a CPU-staged compat…
Back to Articles Enterprise Article Published October 22, 2026 Upvote 3 Kyle Wiggers Ai2Comms Follow allenai 🤗 Models | 📄 Tech Report | 📊 Data | 💻 Code | 🌎 Embeddings Explorer | 🗺️ Interactive story Today, we’re releasi…
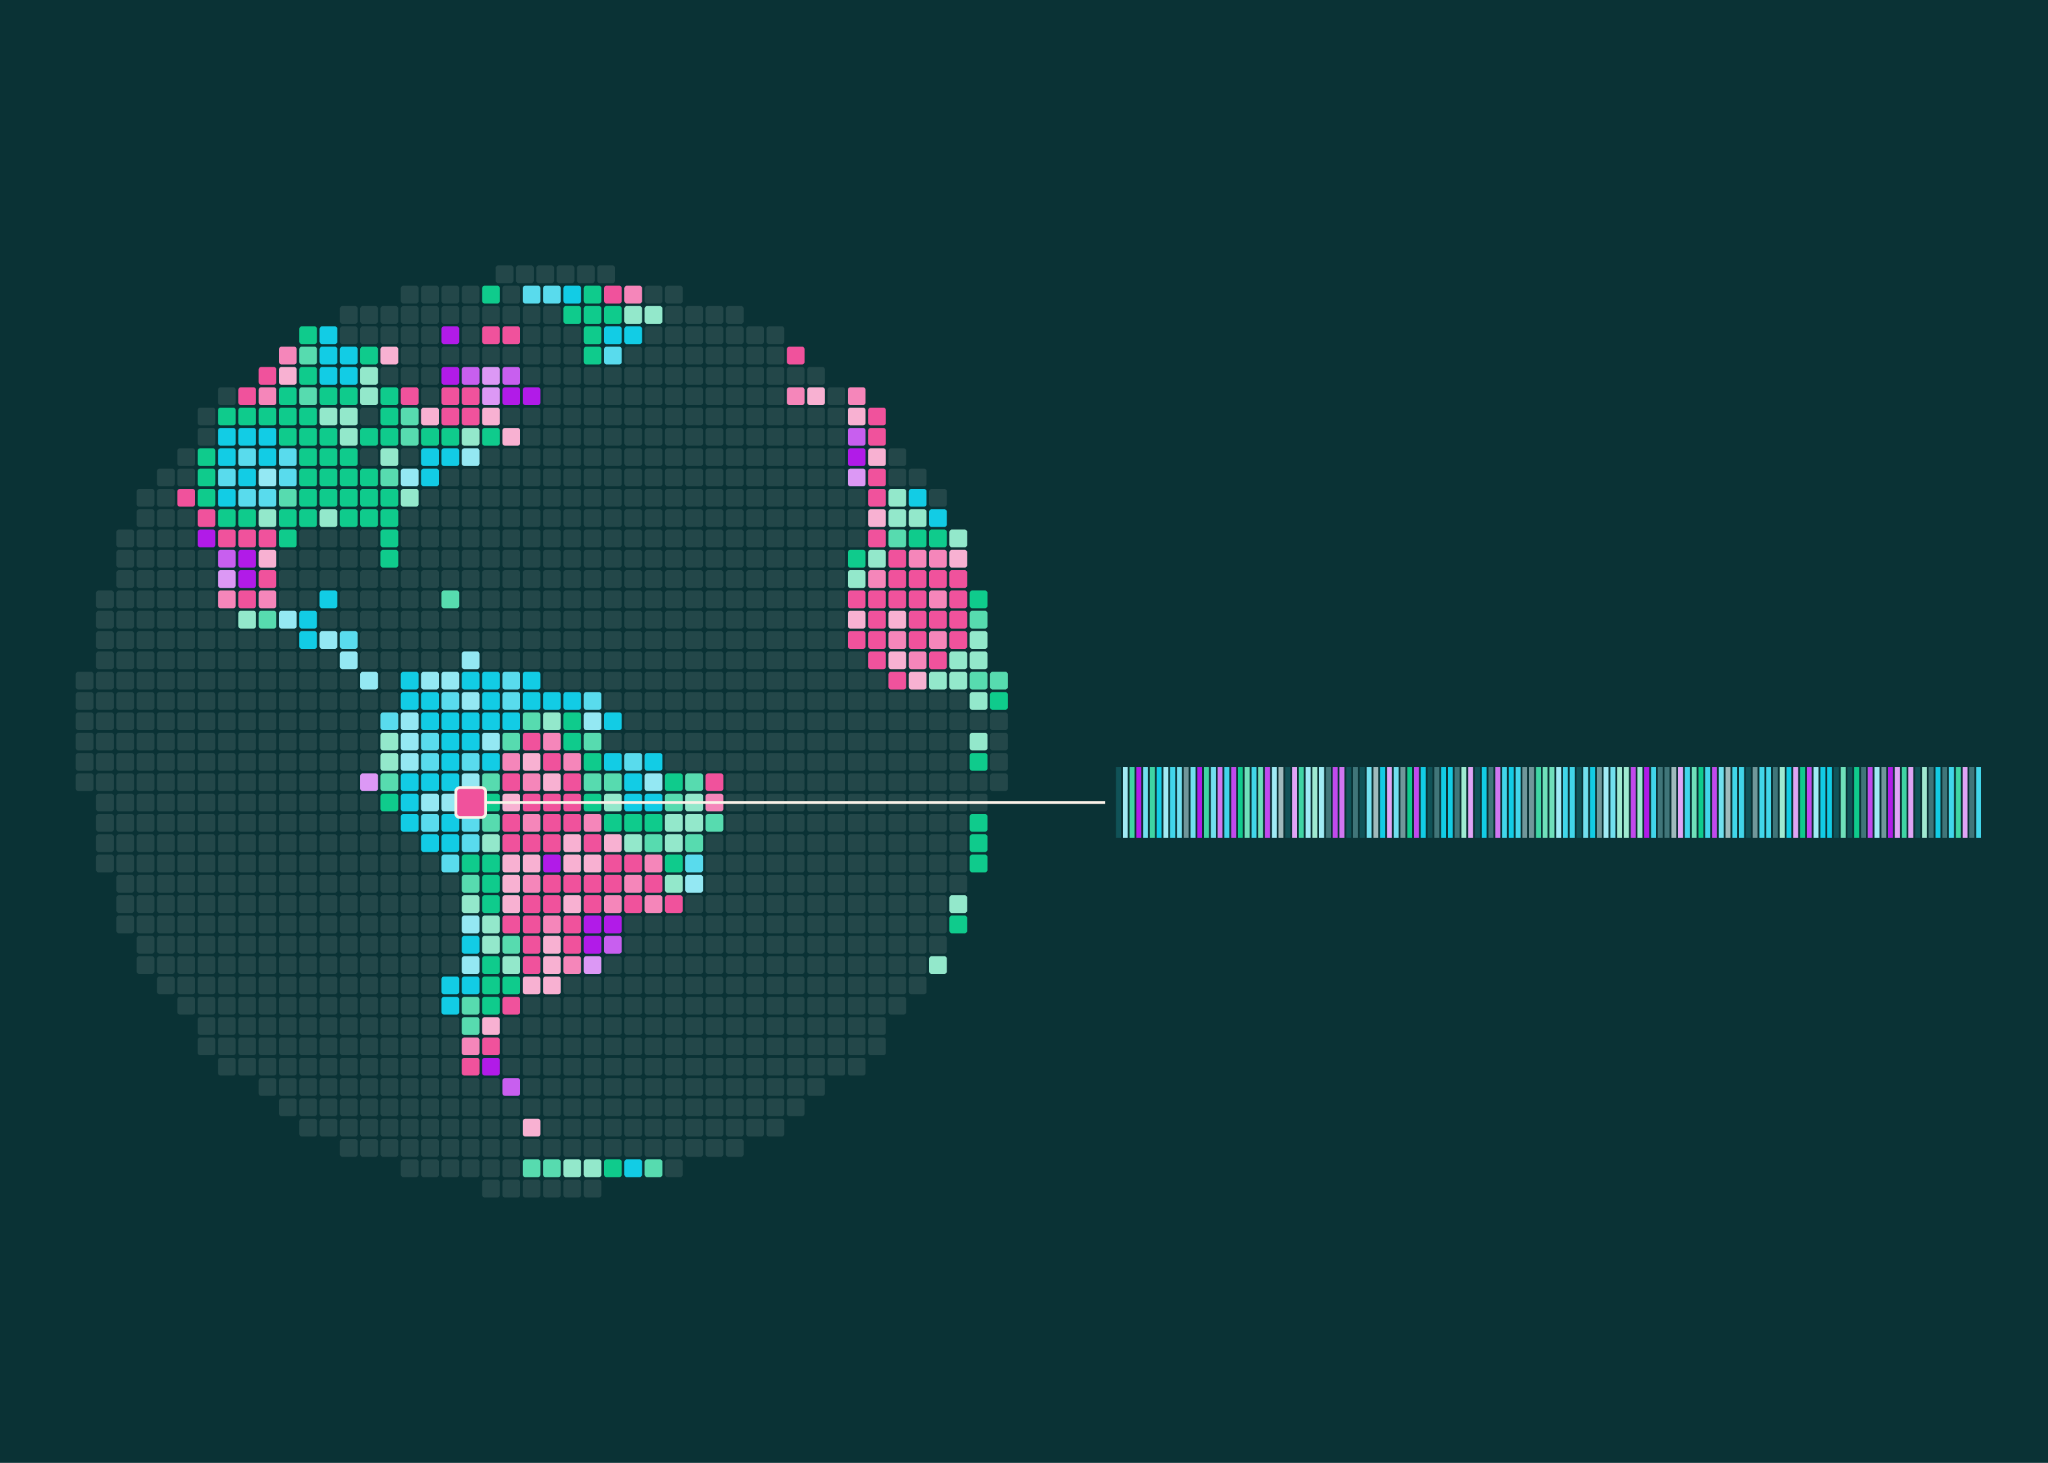
Alongside OlmoEarth v1.3, we’re sharing precomputed, annual embeddings for the whole planet (10m, 64- and 128-dimensions), plus a new browser-based tool to explore and customize maps based on those embeddings — the Olmo…
AI developers aren’t just running a single model anymore—they’re orchestrating multiple models in parallel, chaining inference calls…
NVIDIA DGX Spark now supports official eight-node clusters, scaling unified memory to 1 TB and enabling local execution of frontier-class models such as the full GLM 5.3 (753B) from Z.ai.
A Spark-optimized collective backend called RoCEnante reduces all-reduce latency for tensor-parallel decode on switch-connected clusters, delivering a 4.43x decode speedup at eight nodes compared to 3.05x without it.
Almost 2 months ago, OpenAI introduced Daybreak for Frontline Defenders , a $1B subsidy for access to Daybreak cyber models and products.
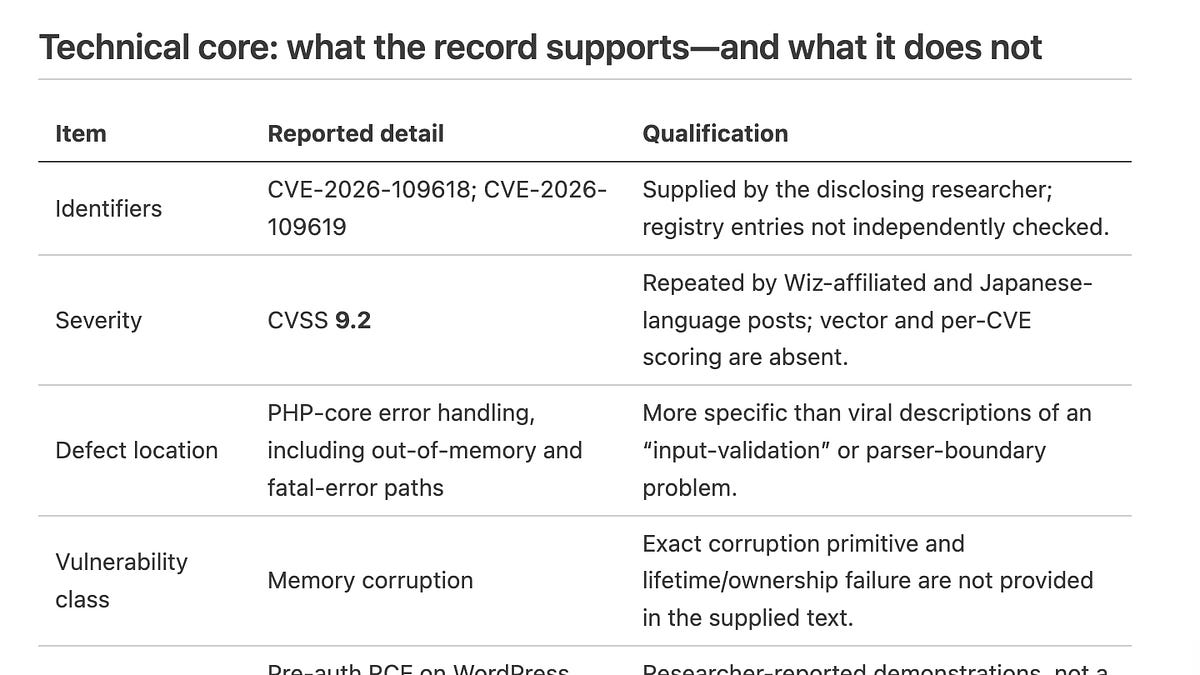
That funding came into use almost immediately, as major vulnerabilities in PHP were independently discovered by two parties: Ryan Austin, a researcher at the security firm Calif, as part of the OpenAI “ Patch the Planet…
NVIDIA Kumo Relational is a pre-trained relational foundation model that makes predictions directly on enterprise databases.
Given a predictive query, it gathers up to 10,000 historical examples as context and predicts outcomes such as churn, demand, or fraud in a single forward pass.